blogs
longer technical writeups
HC vs mHC for computational depth
research: exploring hyper-connections & manifold-constrained HC for improving computational depth
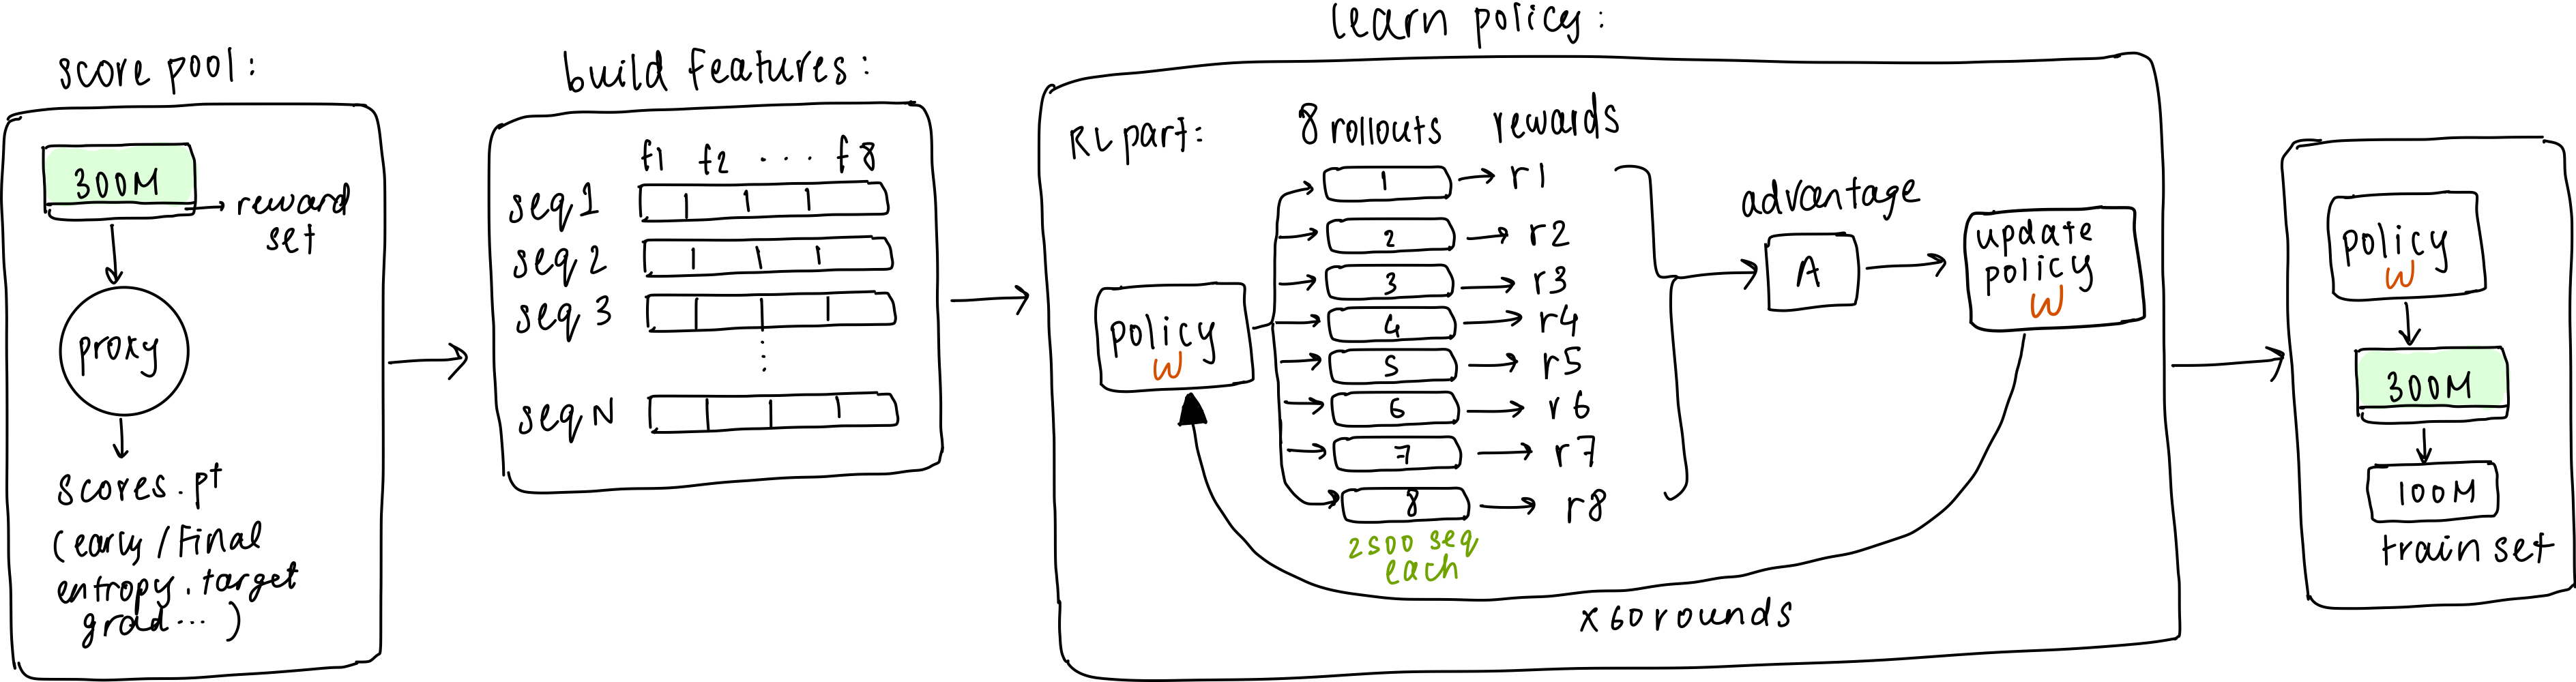
Learning Efficient Data Selection
worklog: can we learn a policy for pretraining data selection
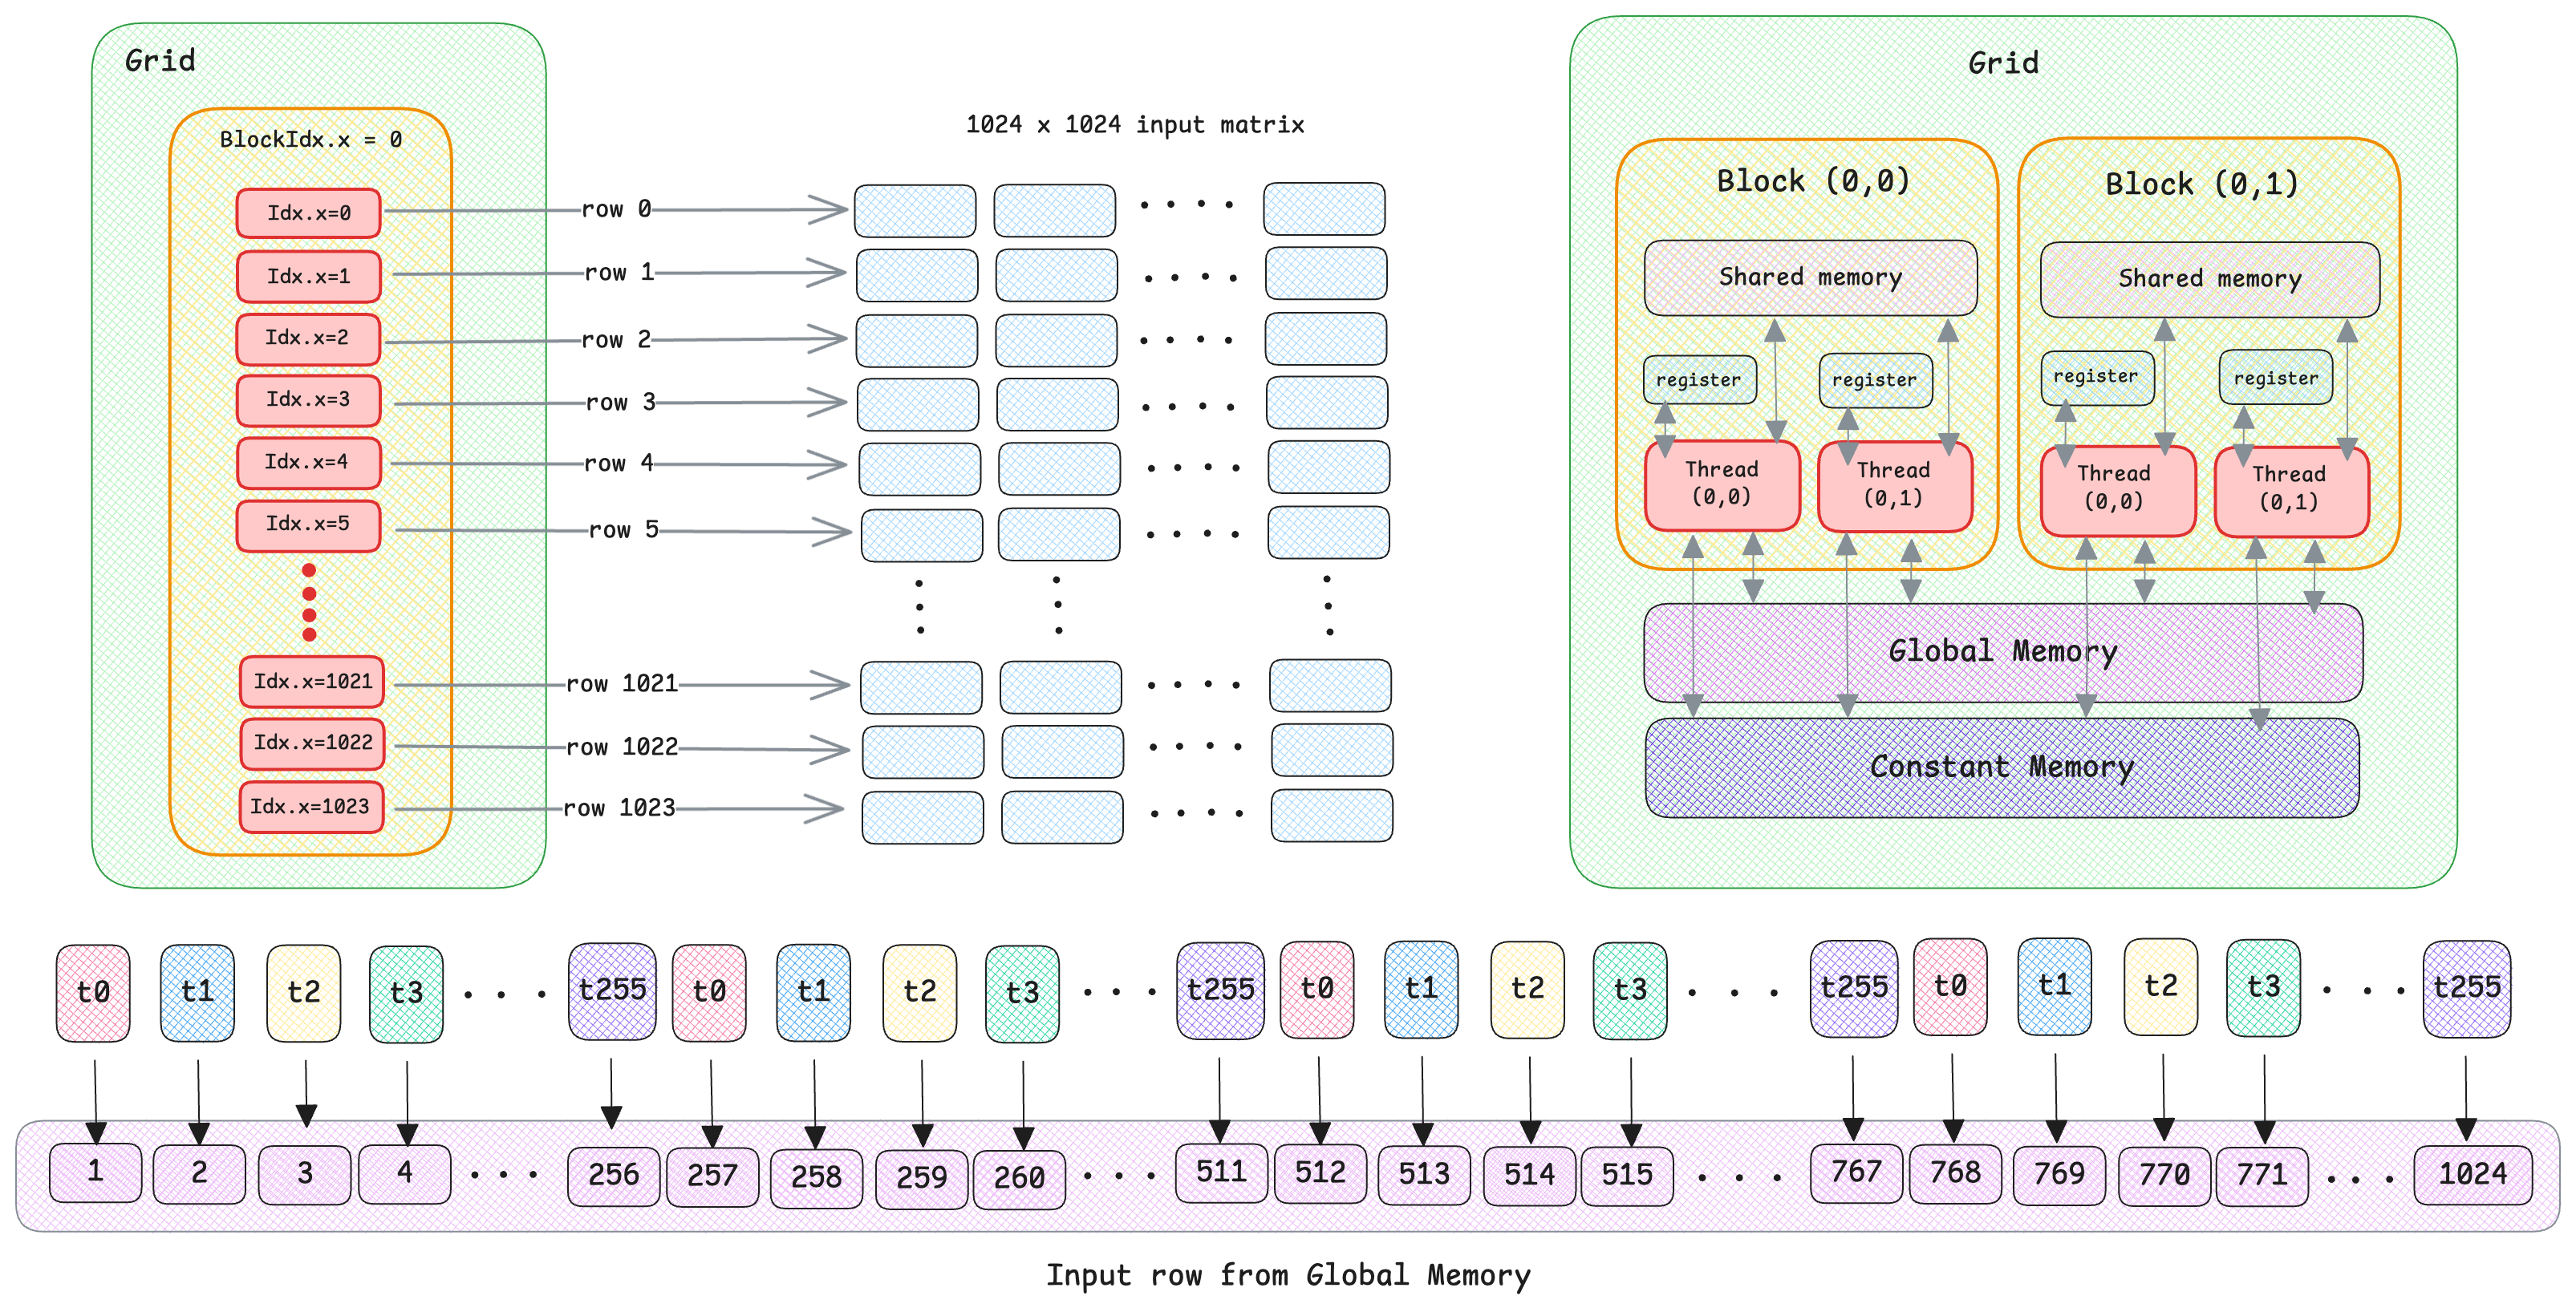
Optimizing Layer Normalization Kernel with CUDA
memory coalescing, shared mem, warp shuffling, and vectorized loading
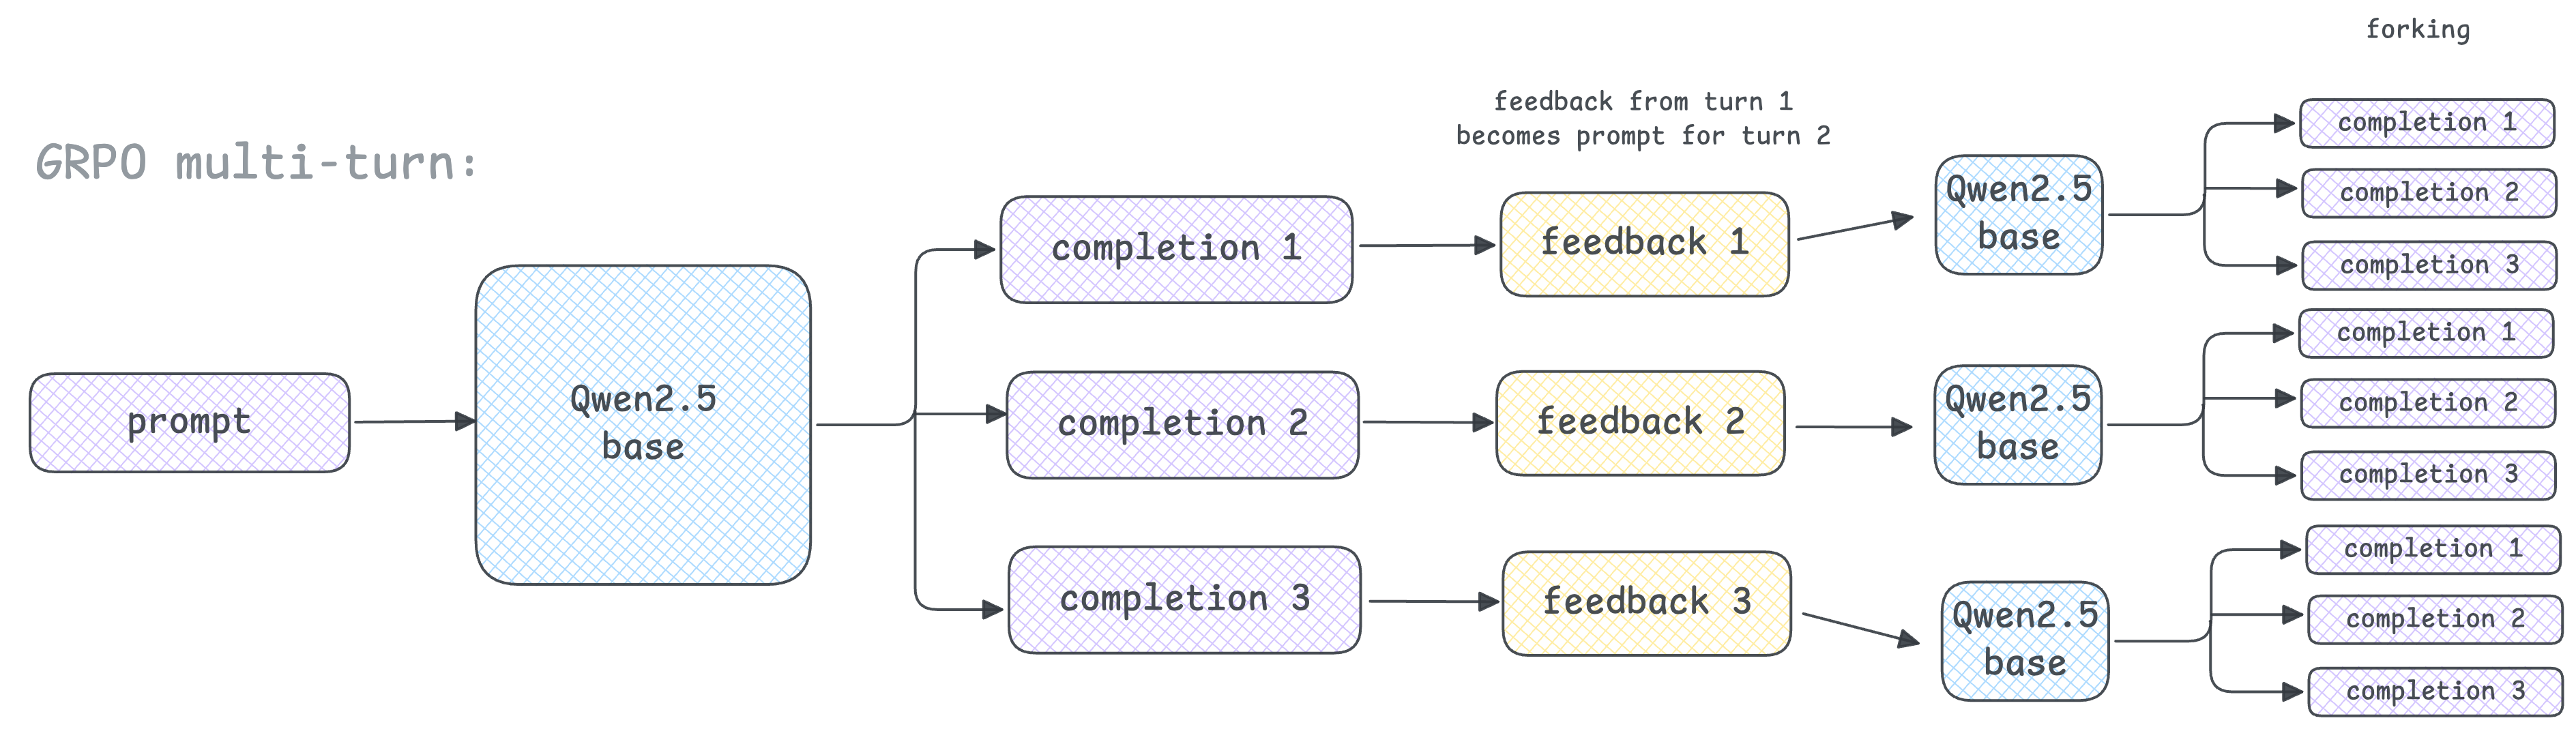
GRPO's Limitations for Reasoning Tasks
a few grpo limitations
Train Qwen3-1.7B to play Wordle with GRPO
training a model to play wordle with grpo on modal for ~$5-6
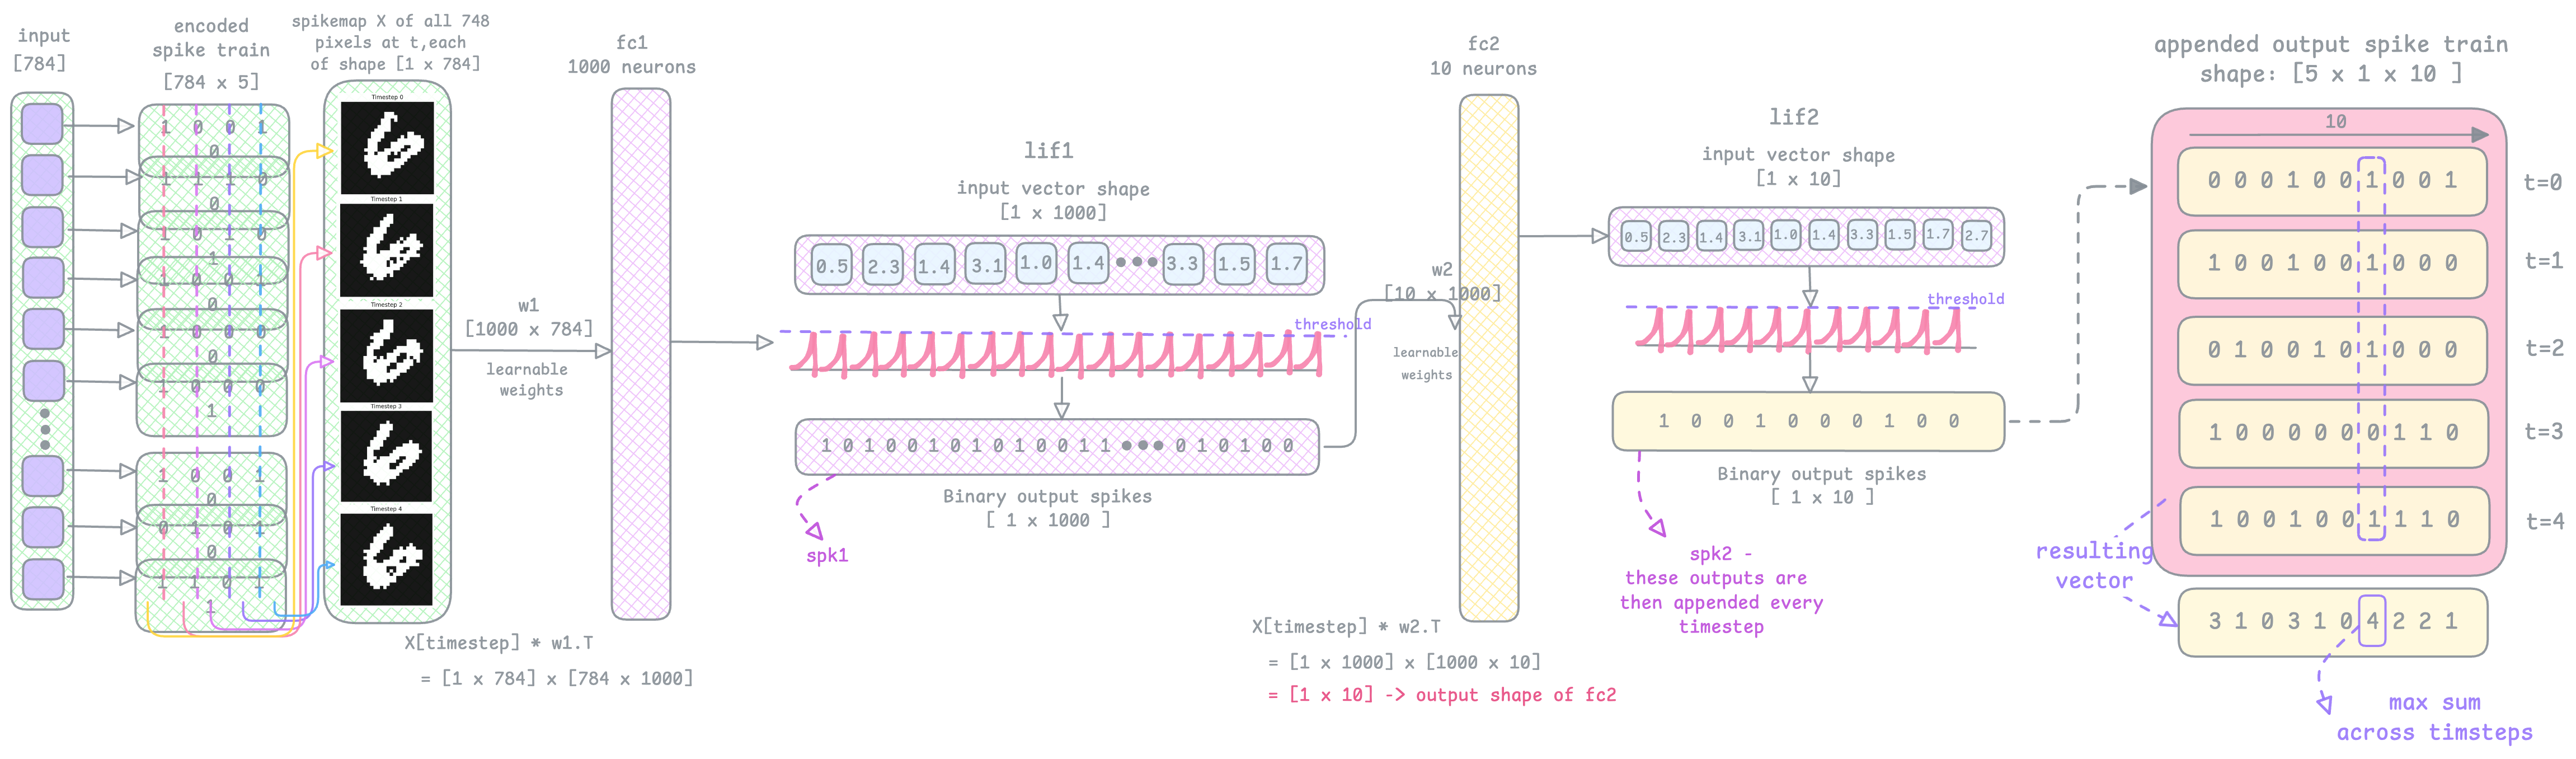
How to Build a Brain (without losing yours)
intro to neuromorphic computing
stuff im learning, reading, paper dumps, etc.
kimi delta attn from first principles
+ linear attention, delta net, and gated delta net
HC outperforms mHC across model depth
mHC solves training instabilities in HC, but collapses effective rank to 1 at deeper layers.
scaling sparse ngram embedding tables needs new infra
breaking down a nanogpt speedrun WR.
Attention residuals for better depth utilization
problems with residual connections & pre-norm
Kimi K2
Notes on pretraining, MuonClip, data, token efficiency.
Marin pretraining
Quick notes on data, architecture, training, kernels, and hardware for the Marin hero run
Optimizer study
Comparing optimizers — order, preconditioners, momentum, EMA, and curvature.
CS336
Notes from Stanford's Language Modeling from Scratch course.
Tensor memory accelerator
Using TMA in the Hopper architecture to load data from global to shared memory.
AdamC
Weight decay tied to the square of the learning rate
some saved links
learning something new everyday