Attention residuals for better depth utilization
problems with residual connections & pre-norm
Standard residuals
With regular residual blocks, the magnitude of the hidden layers can keep growing with every layer as it gets deeper.
- residual skip connections solve the vanishing gradient problem and allow to train deep nets
- Every layer keeps adding some new information to the residual stream so it gradually gets larger
- by the end of model (in deeper layers) the update that's added to the grown residual stream ratio gets smaller so the update is not meaningful, and so the deeper layers get less effective
- updates are diluted in deeper layers
$$h_2 = h_1 + f_1(h_1)$$
$$h_3 = h_1 + f_1(h_1) + f_2(h_2)$$
$$h_4 = h_1 + f_1(h_1) + f_2(h_2) + f_3(h_3)$$
$$h_L = h_l + \sum_{i=l}^{L-1} f_i(h_i)$$
Pre-Norm
- Pre-norm transformers keep the residual stream clean.
- applies norm scaling only to the input going into attn/ffn branch, does not apply norm to the residual stream
- the residual stream is not normalized before being passed over
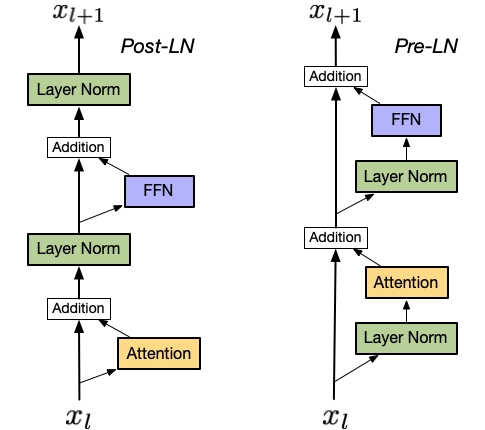
But even with pre-norm the residual connections cause the residual stream to increase in magnitude. Why?
- Because only the update is normalized (the inputs that go into attn or ffn), the residual stream doesn't get normalized so it keeps growing.
- in post norm, the residual stream itself gets normalized.
But why do we still use pre-norm instead of post-norm then?
- pre-norm has an optimization advantage
- since the residual stream is clean, gradients during backprop can be differentiated cleanly
- residual pathway has an identity mapping
- “gradient highway”
Attention residual
- regular residuals sums every previous layer's representation, and the current layer only has access to the immediate layers input, it cannot access each layer separately
- attn res lets the current layer choose which earlier representation it wants
- every layer representation now depends on a learnable weight value
$$h_2 = \alpha_{0 \to 2} \cdot h_1 + \alpha_{1 \to 2} \cdot f_1(h_1)$$
$$h_3 = \alpha_{0 \to 3} \cdot h_1 + \alpha_{1 \to 3} \cdot f_1(h_1) + \alpha_{2 \to 3} \cdot f_2(h_2)$$
- replaces the fixed accumulation with softmax attention
- Attn res mitigates pre-norm dilution
- to find Alpha, do softmax attention
- normalize the queries with RMS norm before
How does Attention residual help reduce pre-norm dilution?
- $x_l = 0.05v_3 + 0.7v_{12} + 0.25v_{18}$
- with attn residual magnitude of hidden state does not scale linearly with depth since layers learn weights for each representation
Block Attention Residual
- partition the layers into N blocks,
- within each block the layers outputs are reduced into a single representation